User agent parser
Parse details from user agent strings.
User agent parser is a free tool that analyzes a user agent string and returns its browser, operating system, and device type.
Why parse a user agent before shipping a change?
Parsing a user agent helps you check how a request is likely to be classified before you deploy browser-specific handling, analytics rules, or device reporting. It turns a dense header value into a few fields that are easier to compare.
Common workflow uses include:
- Investigating why an authentication flow fails only in a particular browser family.
- Checking user agent values copied from application, CDN, or web server logs.
- Normalizing third-party event data before importing it into an analytics system.
- Reviewing whether monitoring traffic is being grouped with desktop or mobile visits.
- Confirming that a test device sends the browser and operating system information you expect.
Parsing is less useful when the code can test the required capability directly. For example, checking whether an API exists is usually more dependable than assuming support from a browser name. It is also unnecessary when a user agent appears only in machine-to-machine traffic and nobody will use the parsed categories.
What happens when I enter a user agent string?
The tool sends the value to the server over HTTPS, parses it there, and returns three fields. The submitted user agent string is not stored.
- Paste the complete header value into the User agent field.
- Run the parser without removing tokens that look repetitive. Compatibility tokens often affect classification.
- Review Browser, Operating system, and Device type together rather than treating one field as definitive.
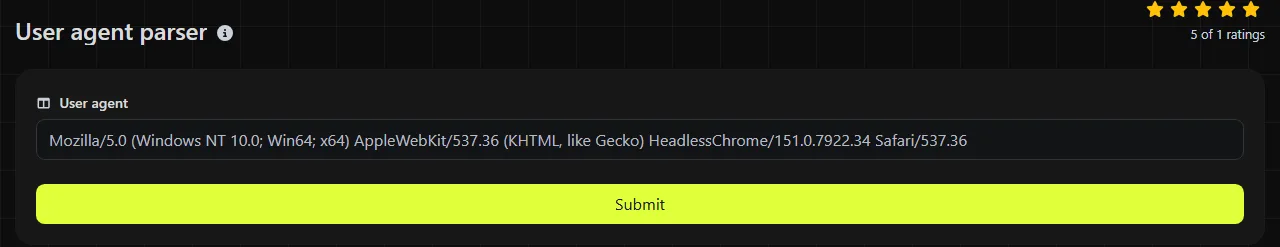
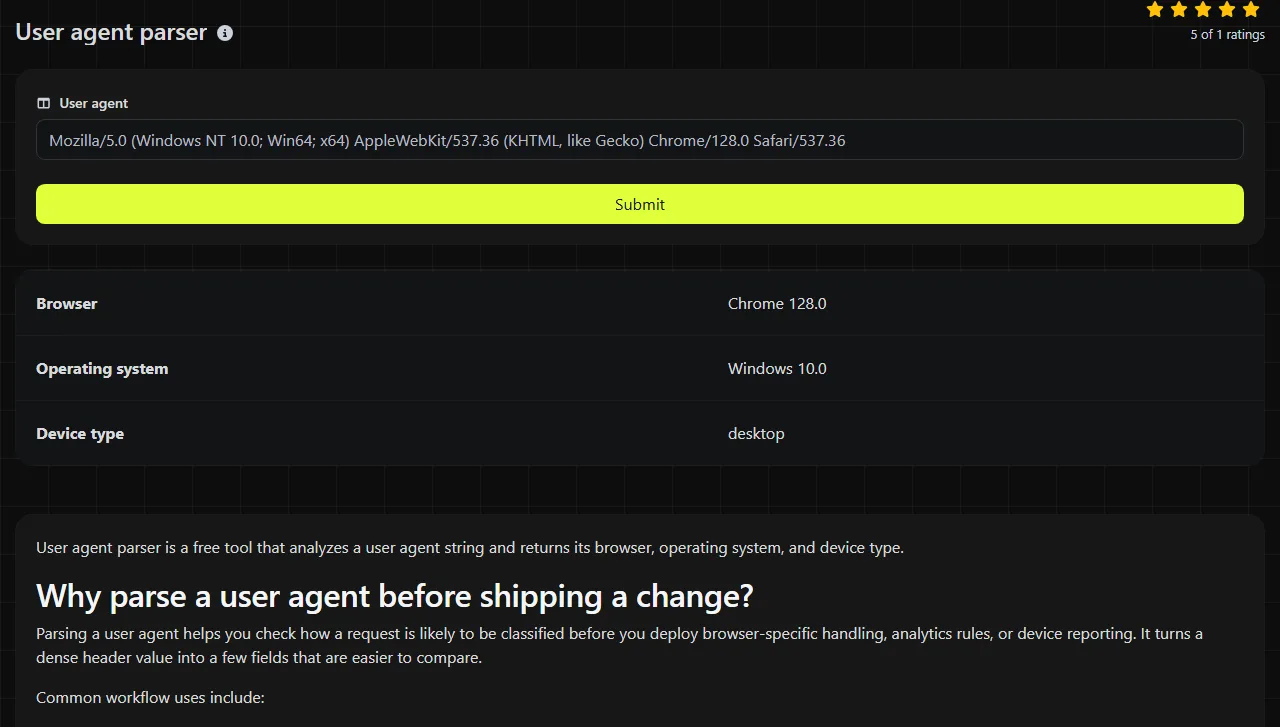
Browser identifies the browser family that the parser associates with the input. Operating system reports the available platform information. Device type gives a broad device category, such as desktop or mobile, when the string contains enough recognizable evidence.
These are classifications, not verified facts about the requesting hardware. User agent strings are supplied by clients and can be changed, shortened, frozen, or copied from another client.
Two small input and result examples
Consider this shortened desktop-style input:
Input: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 Chrome/122.0.0.0 Safari/537.36
Broad result: Browser is Chrome, operating system is Windows, and device type is desktop. Exact version wording can depend on the parser because the Windows NT 10.0 token does not distinguish every current Windows release.
A mobile Safari-style example looks different:
Input: Mozilla/5.0 (iPhone; CPU iPhone OS 17_3 like Mac OS X) AppleWebKit/605.1.15 Version/17.3 Mobile/15E148 Safari/604.1
Broad result: Browser is Safari, operating system is iOS, and device type is mobile. Tokens such as AppleWebKit, Mobile, and Safari describe different parts of the client, so repeated product names do not necessarily indicate an error.
Real user agent strings are often longer than these examples. Their ordering and punctuation matter because parsers compare token patterns, parenthesized platform comments, product versions, and compatibility markers.
How reliable is browser and device detection?
User agent detection is useful for classification, but it cannot prove which software or hardware made a request. Browsers commonly include compatibility tokens associated with other browsers, and automated clients can send any value they choose.
A parsed result may also be incomplete for a legitimate client. Some browsers reduce the detail in their user agent strings to limit passive fingerprinting. In other cases, an embedded web view, in-app browser, privacy tool, or proxy changes the original header.
Do not use a parsed user agent as the only basis for security decisions, access control, fraud detection, or identity verification. A request claiming to come from a familiar browser is not authenticated by that claim. For front-end behavior, capability detection and responsive CSS are commonly better choices than device-name branching.
Which input problems can produce an unclear result?
Incomplete, malformed, or unusual input can produce broad or inaccurate classifications because a parser can only interpret the tokens it receives. Unlike a syntax validator, a user agent parser cannot determine whether the client is telling the truth.
- Empty input: There is no browser, operating system, or device evidence to classify.
- Numbers only: A version number without a product token has no dependable browser meaning.
- Extra line breaks: A copied HTTP header may include wrapping from a log viewer. Raw header field values should not contain arbitrary line breaks.
- Missing punctuation: Removing slashes, parentheses, semicolons, or spaces can change how product and platform tokens are recognized.
- Accented or non-Latin characters: These are unusual in conventional product tokens. Their presence may come from a custom client, encoding problem, or log transformation.
- Very long input: Length alone does not make a user agent more reliable. Extensions, embedded apps, and vendor components may add many tokens.
When debugging, compare the value with the raw User-Agent request header rather than a reformatted spreadsheet cell or truncated dashboard entry. If the value came from a URL or query parameter, a URL parser can help check whether it was decoded correctly before analysis.
Frequently asked questions
Can a user agent reveal the exact Windows version?
Often, no. Windows 10 and Windows 11 browsers may both include the Windows NT 10.0 token, so the traditional user agent does not reliably separate them. Client hints can provide additional platform version information when the browser and server participate in that mechanism.
Why can an iPad be classified like a Mac?
Some iPads use a desktop-style user agent that resembles macOS, especially when requesting desktop sites. Touch support, screen behavior, or client hints may provide better evidence, but those signals are outside a plain user agent string.
Is a user agent string personal data?
A user agent usually describes software and platform characteristics rather than directly naming a person. Combined with IP addresses, timestamps, language settings, or other signals, however, it can contribute to identifying or fingerprinting a visitor. Apply the retention and access rules used for other request-log data.
Should I store the raw value or only the parsed fields?
Store the raw value only when you have a defined debugging or analytics need and your data policy permits it. Keeping it allows later reprocessing when parser rules change, while storing only normalized fields reduces detail and storage. Set a retention period instead of keeping request metadata indefinitely.
Can I parse user agents in a command-line or backend workflow?
Yes. Established user agent parsing libraries are available for common server-side languages and can process log files in batches. Avoid maintaining a few ad hoc regular expressions because browser tokens overlap and change over time. Use the same library and rule version across a pipeline when consistent categorization matters.
Popular tools
Create a WhatsApp chat link from a phone number, with an optional prefilled message.