URL extractor
Extract http/https URLs from any kind of text content.
URL extractor is a free tool that finds HTTP and HTTPS URLs in pasted text and reports how many it matched.
Where are extracted URLs useful?
Extracted URLs are useful when links are mixed with comments, labels, timestamps, or other text that you do not need. Pulling them out manually is slow and makes it easy to miss a link.
- Collect links from a Slack conversation before moving them into a project document.
- Review URLs in Zendesk ticket exports without reading every message again.
- Prepare a link column from a CSV exported by Google Sheets or Microsoft Excel.
- Inventory old page addresses during a WordPress migration or content audit.
- Separate destination URLs from campaign notes before preparing mail-merge data.
Keep the original text until the URL extraction job is finished. An extracted link may need the surrounding ticket number, page title, or customer name to make sense later.
A short extraction workflow
- Paste the source text containing the links.
- Run the extraction.
- Check the reported Count against the number of links you expected.
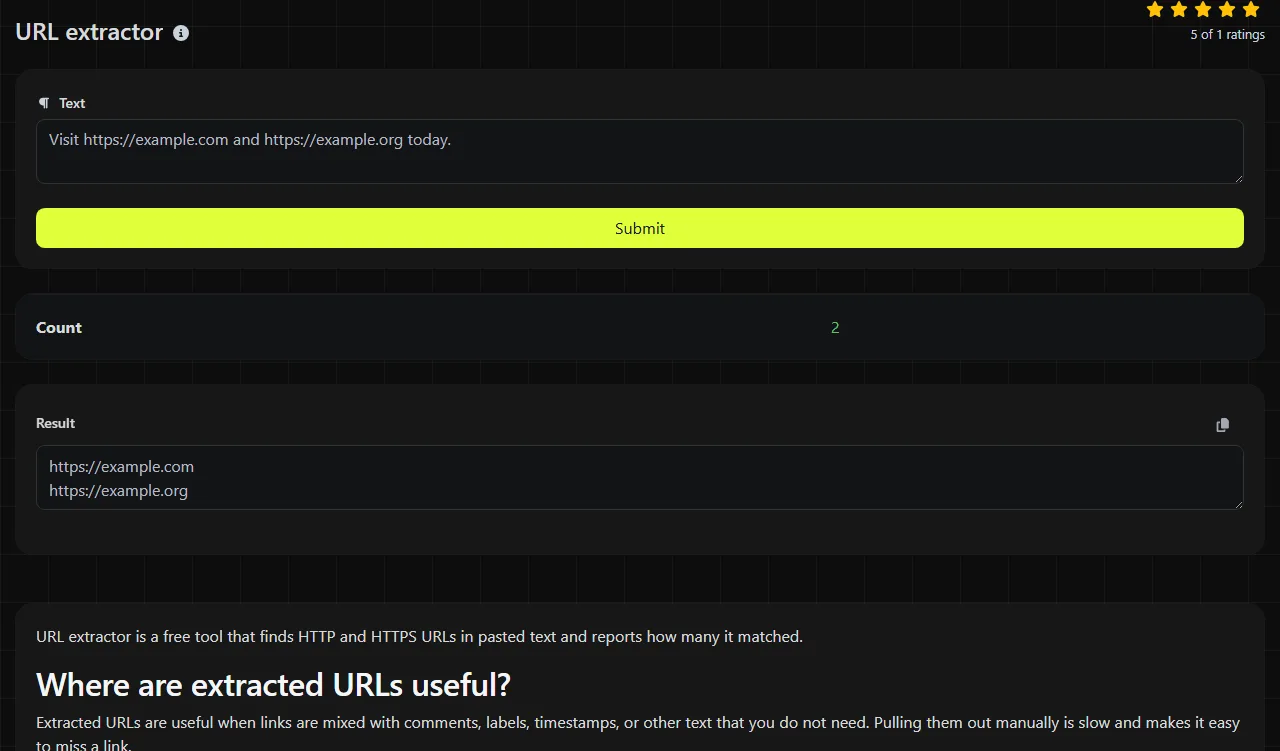
For example, consider this input:
Review https://docs.example.com/setup and monitor http://status.example.org
The matching URLs are https://docs.example.com/setup and http://status.example.org, with a count of 2. Text that does not begin with an HTTP or HTTPS scheme is outside the intended match.
For large URL extraction jobs, try a short representative section first. It can reveal unusual punctuation, HTML markup, or broken line wrapping before you process the full block.
What does the Count result mean?
Count tells you how many URL matches the tool found in the submitted text. The tool uses regular-expression matching on the server to locate HTTP and HTTPS patterns.
The URL match count is useful as a quick reconciliation check. If a spreadsheet export is expected to contain 40 links and the result is 37, inspect blank cells, malformed schemes, or URLs broken across lines. Do not treat the count as proof that every destination is reachable or safe. Pattern matching identifies URL-shaped content; it does not establish the status, ownership, or reputation of the destination.
Which parts of an extracted URL should you review?
Review punctuation, parameters, fragments, and encoded characters before reusing extracted URLs. These elements can be valid parts of a URL, but copied prose and source code can make the boundaries unclear.
- Spaces: Raw spaces commonly end a URL match. A valid URL may represent spaces with percent encoding such as %20.
- Sentence punctuation: A period, comma, parenthesis, or quotation mark next to a link may belong to the sentence rather than the URL.
- Query parameters: Everything after ? and before #, or through the end of the URL if there is no #, may contain search terms, campaign tags, session data, or other values.
- Fragments: A fragment after # identifies a secondary resource. In HTML, it commonly points to a location within a page and may be needed for the link to open at the intended section.
- International characters: Domain names may appear in Punycode, while paths may contain Unicode characters or percent-encoded bytes.
- Numbers: Numbers are valid in domains, paths, parameters, and port numbers. Their presence does not make a URL malformed.
An empty input has no URL content to match.
Server processing and tool scope
The extraction takes place on the server. Your input travels to the server over HTTPS and is not stored.
The extractor does not replace a link checker, security scanner, HTML parser, or web crawler. It works on the text you submit and looks for HTTP and HTTPS URLs. If the same source also contains email addresses, the Email extractor is better suited to that separate task. The Text separator can help when the next system requires a specific delimiter.
Common questions about extracting URLs
Can I extract links from a PDF file?
You can extract links from text copied out of a searchable PDF. To use the URL extractor with a scanned PDF, you usually need to run optical character recognition first because its pages may contain images rather than selectable text.
How do HTML entities affect URL extraction?
HTML may represent an ampersand as an HTML entity. Copying from the rendered page may produce a normal ampersand, while copying source code may preserve the entity.
Are international domain names safe to reuse?
Internationalized domain names are valid, but visually similar Unicode characters can be used in misleading domains. Check the hostname carefully, especially before opening a link or adding it to public content.
Should I paste signed cloud-storage links?
A signed URL can contain temporary access credentials in its query parameters. Although input is sent over HTTPS and is not stored by this tool, avoid pasting sensitive links unless extraction is necessary and you are authorized to handle them.
Can I extract URLs without an online tool?
Yes. Command-line regular expressions, PowerShell, spreadsheet formulas, and scripts can find URL patterns locally. Those options are useful for repeatable processing, but the pattern still needs careful handling around punctuation, HTML entities, and wrapped lines.
Popular tools
Create a WhatsApp chat link from a phone number, with an optional prefilled message.